
GelSlim 5.0: Unifying Vision and Touch with a Single Fingertip Camera
Traducción pendiente. Se muestra el resumen en inglés.
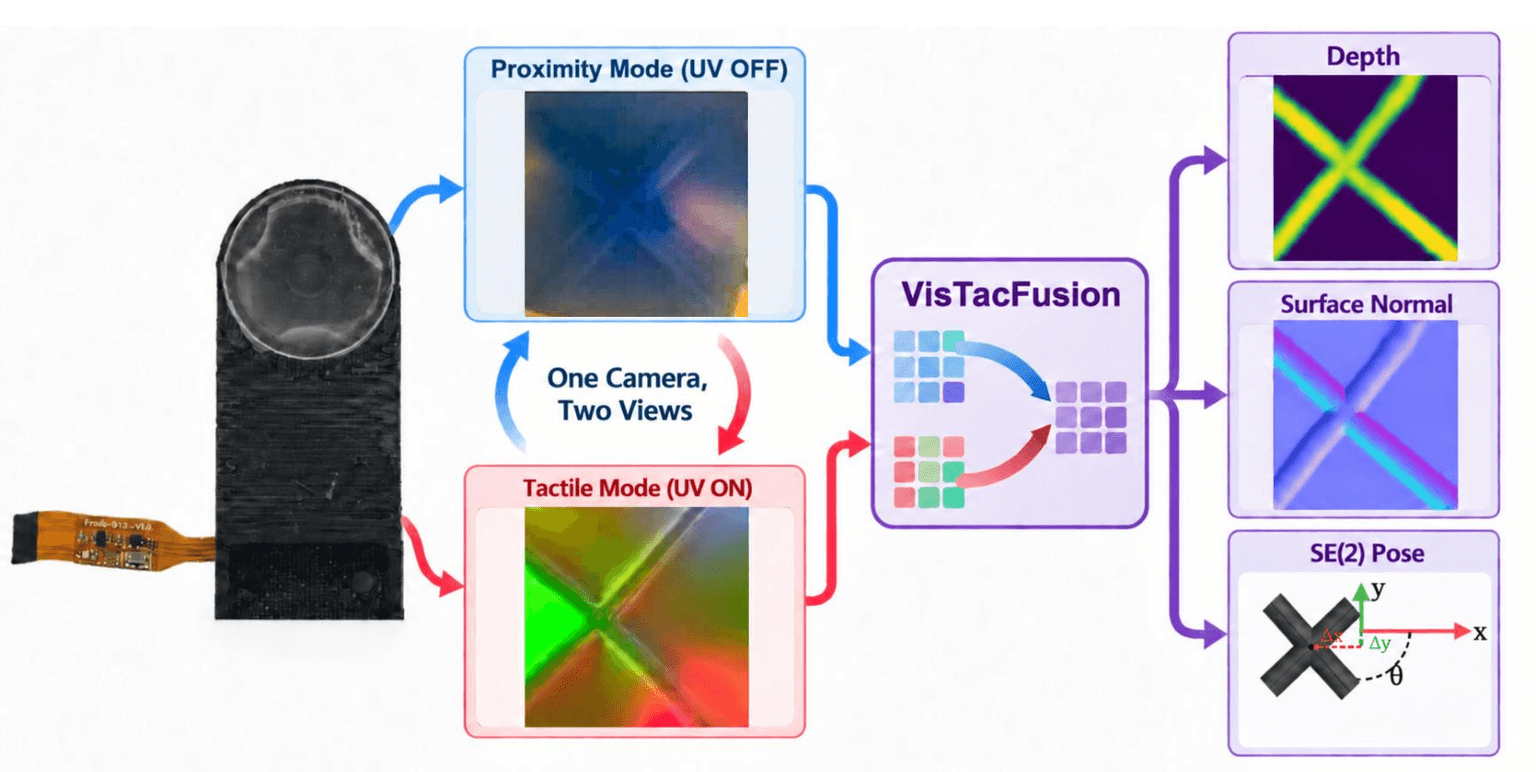
GelSlim 5.0 uses one fixed fingertip camera and a UV-responsive contact layer to capture visual and tactile images sequentially by switching illumination. The VisTacFusion transformer estimates planar object pose and contact depth and surface normals, with modality dropout supporting paired or single-modality inputs. On real validation data from 12 known objects, paired inputs reduced depth MSE by 61.2% versus tactile-only inference and 93.7% versus visual-only inference.
A short source-linked brief, prepared and localized with AI assistance. The original article is not republished.
Paper details
Xiangdong Wang, I-Hsuan Huang, Xiaohao Xu, Xili Yi, Nima Fazeli, Xiaonan Huang
arXiv: 2610.31334 · v1
Preprints may not have completed peer review.